Data Engineering
Coming Soon
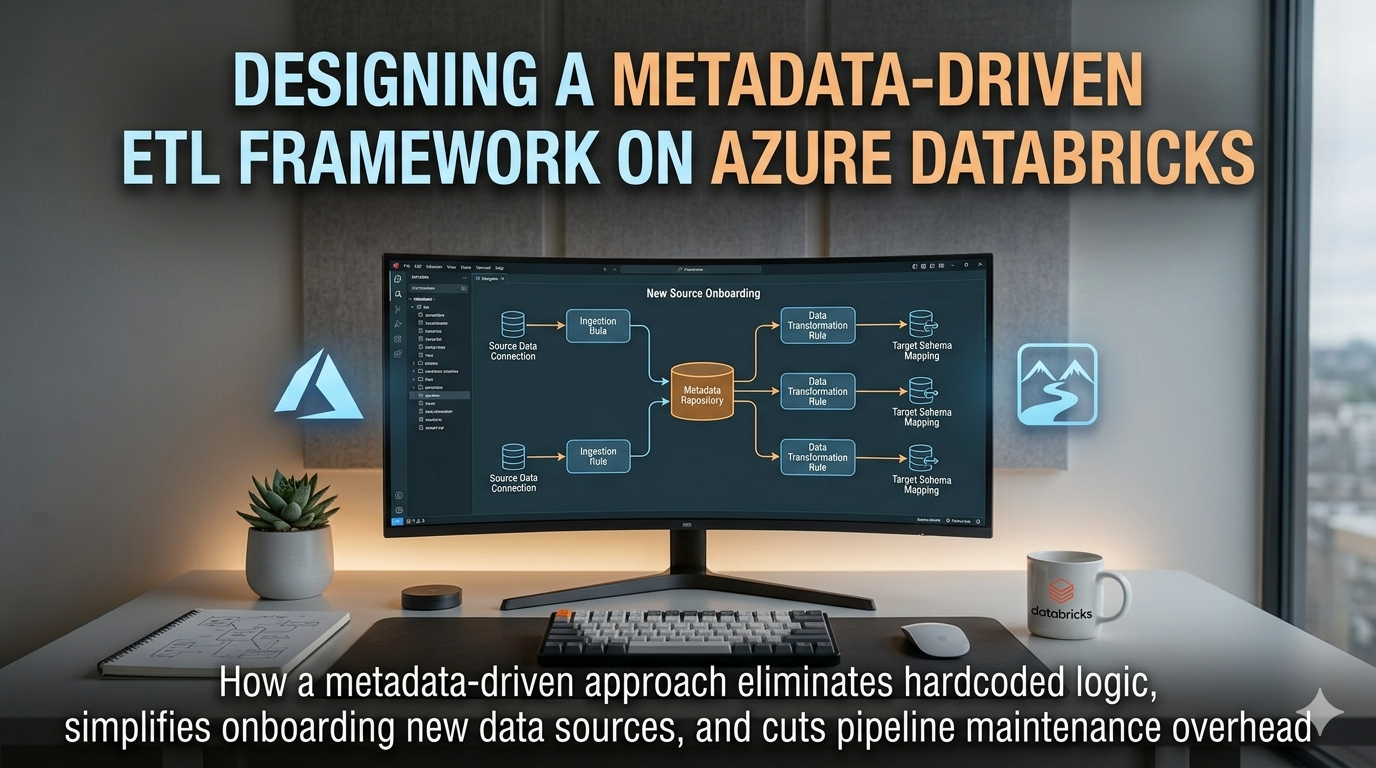
Designing a Metadata-Driven ETL Framework on Azure Databricks
How a metadata-driven approach eliminates hardcoded logic, simplifies onboarding new data sources, and cuts pipeline maintenance overhead.
DevOps
Coming Soon
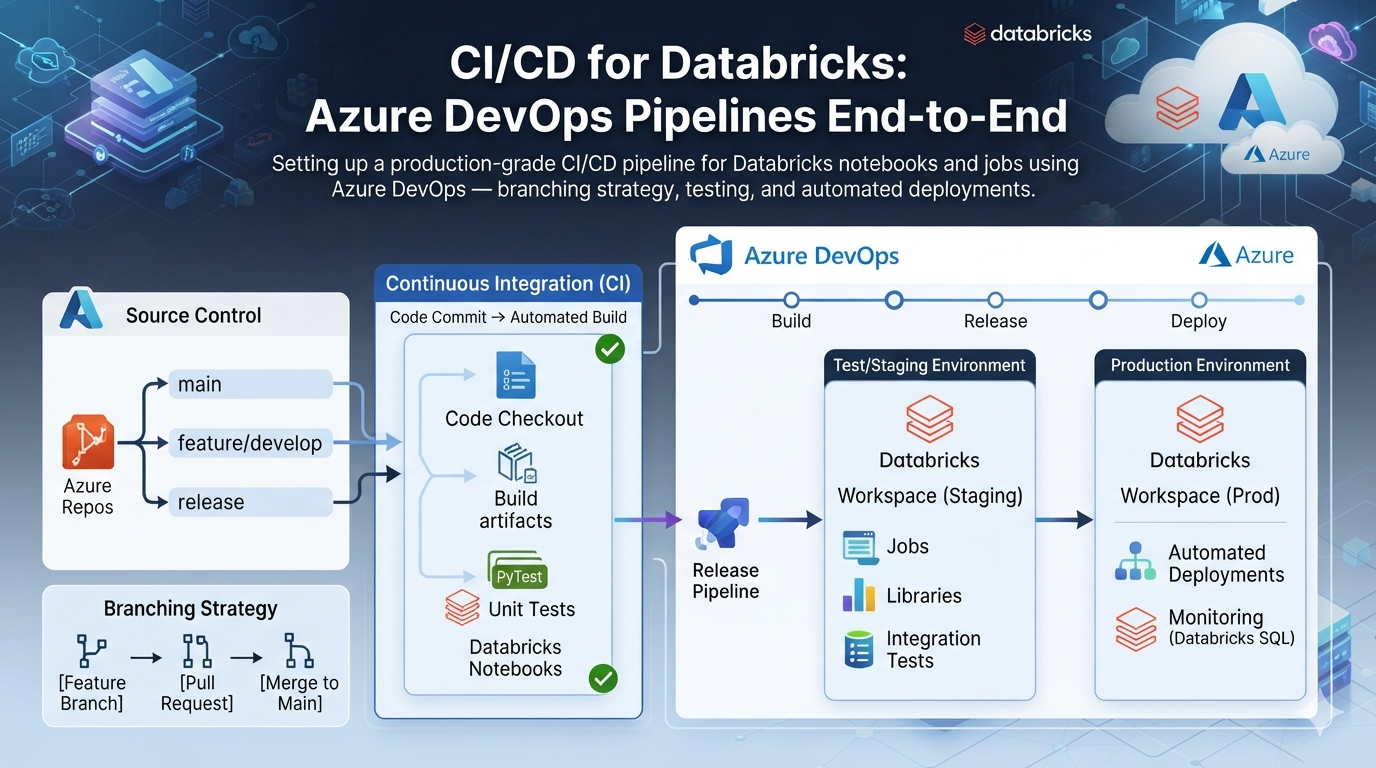
CI/CD for Databricks: Azure DevOps Pipelines End-to-End
Setting up a production-grade CI/CD pipeline for Databricks notebooks and jobs using Azure DevOps — branching strategy, testing, and automated deployments.
AI / LLM
Coming Soon
GitHub Copilot as a Migration Accelerator: Real Numbers
An honest look at how GitHub Copilot reduced Informatica-to-PySpark migration effort by 40–60% — what it did well, where it struggled, and how to prompt it effectively.